Overview
Tandemn is a global planner for LLM inference fleets. It computes deployment plans for online and batch jobs across clusters, clouds, regions, and accelerator types. Koi, the planner, uses job intent, available resources, and observed serving metrics to evaluate deployment configurations and placements against capacity, latency, deadline, and reconfiguration constraints. The research found that feasible configurations for one profiled 70B model on the same accelerator family varied by 4.4× in throughput and 7.5× in cost per token, illustrating why static profiles may not be sufficient for fleet-wide planning.
These docs describe Koi and Tandemn’s control-plane architecture. Koi uses job intent, fleet resource state, and serving telemetry to produce deployment plans. The control plane coordinates global resource state and plan application by per-cluster operators. See Tandemn Architecture and Tandemn Planner (Koi) for details.
How the pieces fit together
Section titled “How the pieces fit together”A team describes a job’s model, workload, and serving objective, such as latency targets for online inference or a deadline for batch work. Koi combines those jobs with a global view of cluster resources and deployment telemetry, then proposes a plan for the fleet. In the reference architecture, per-cluster operators apply that plan through the existing serving and orchestration stack. Observed behavior feeds back into Koi to inform later decisions.
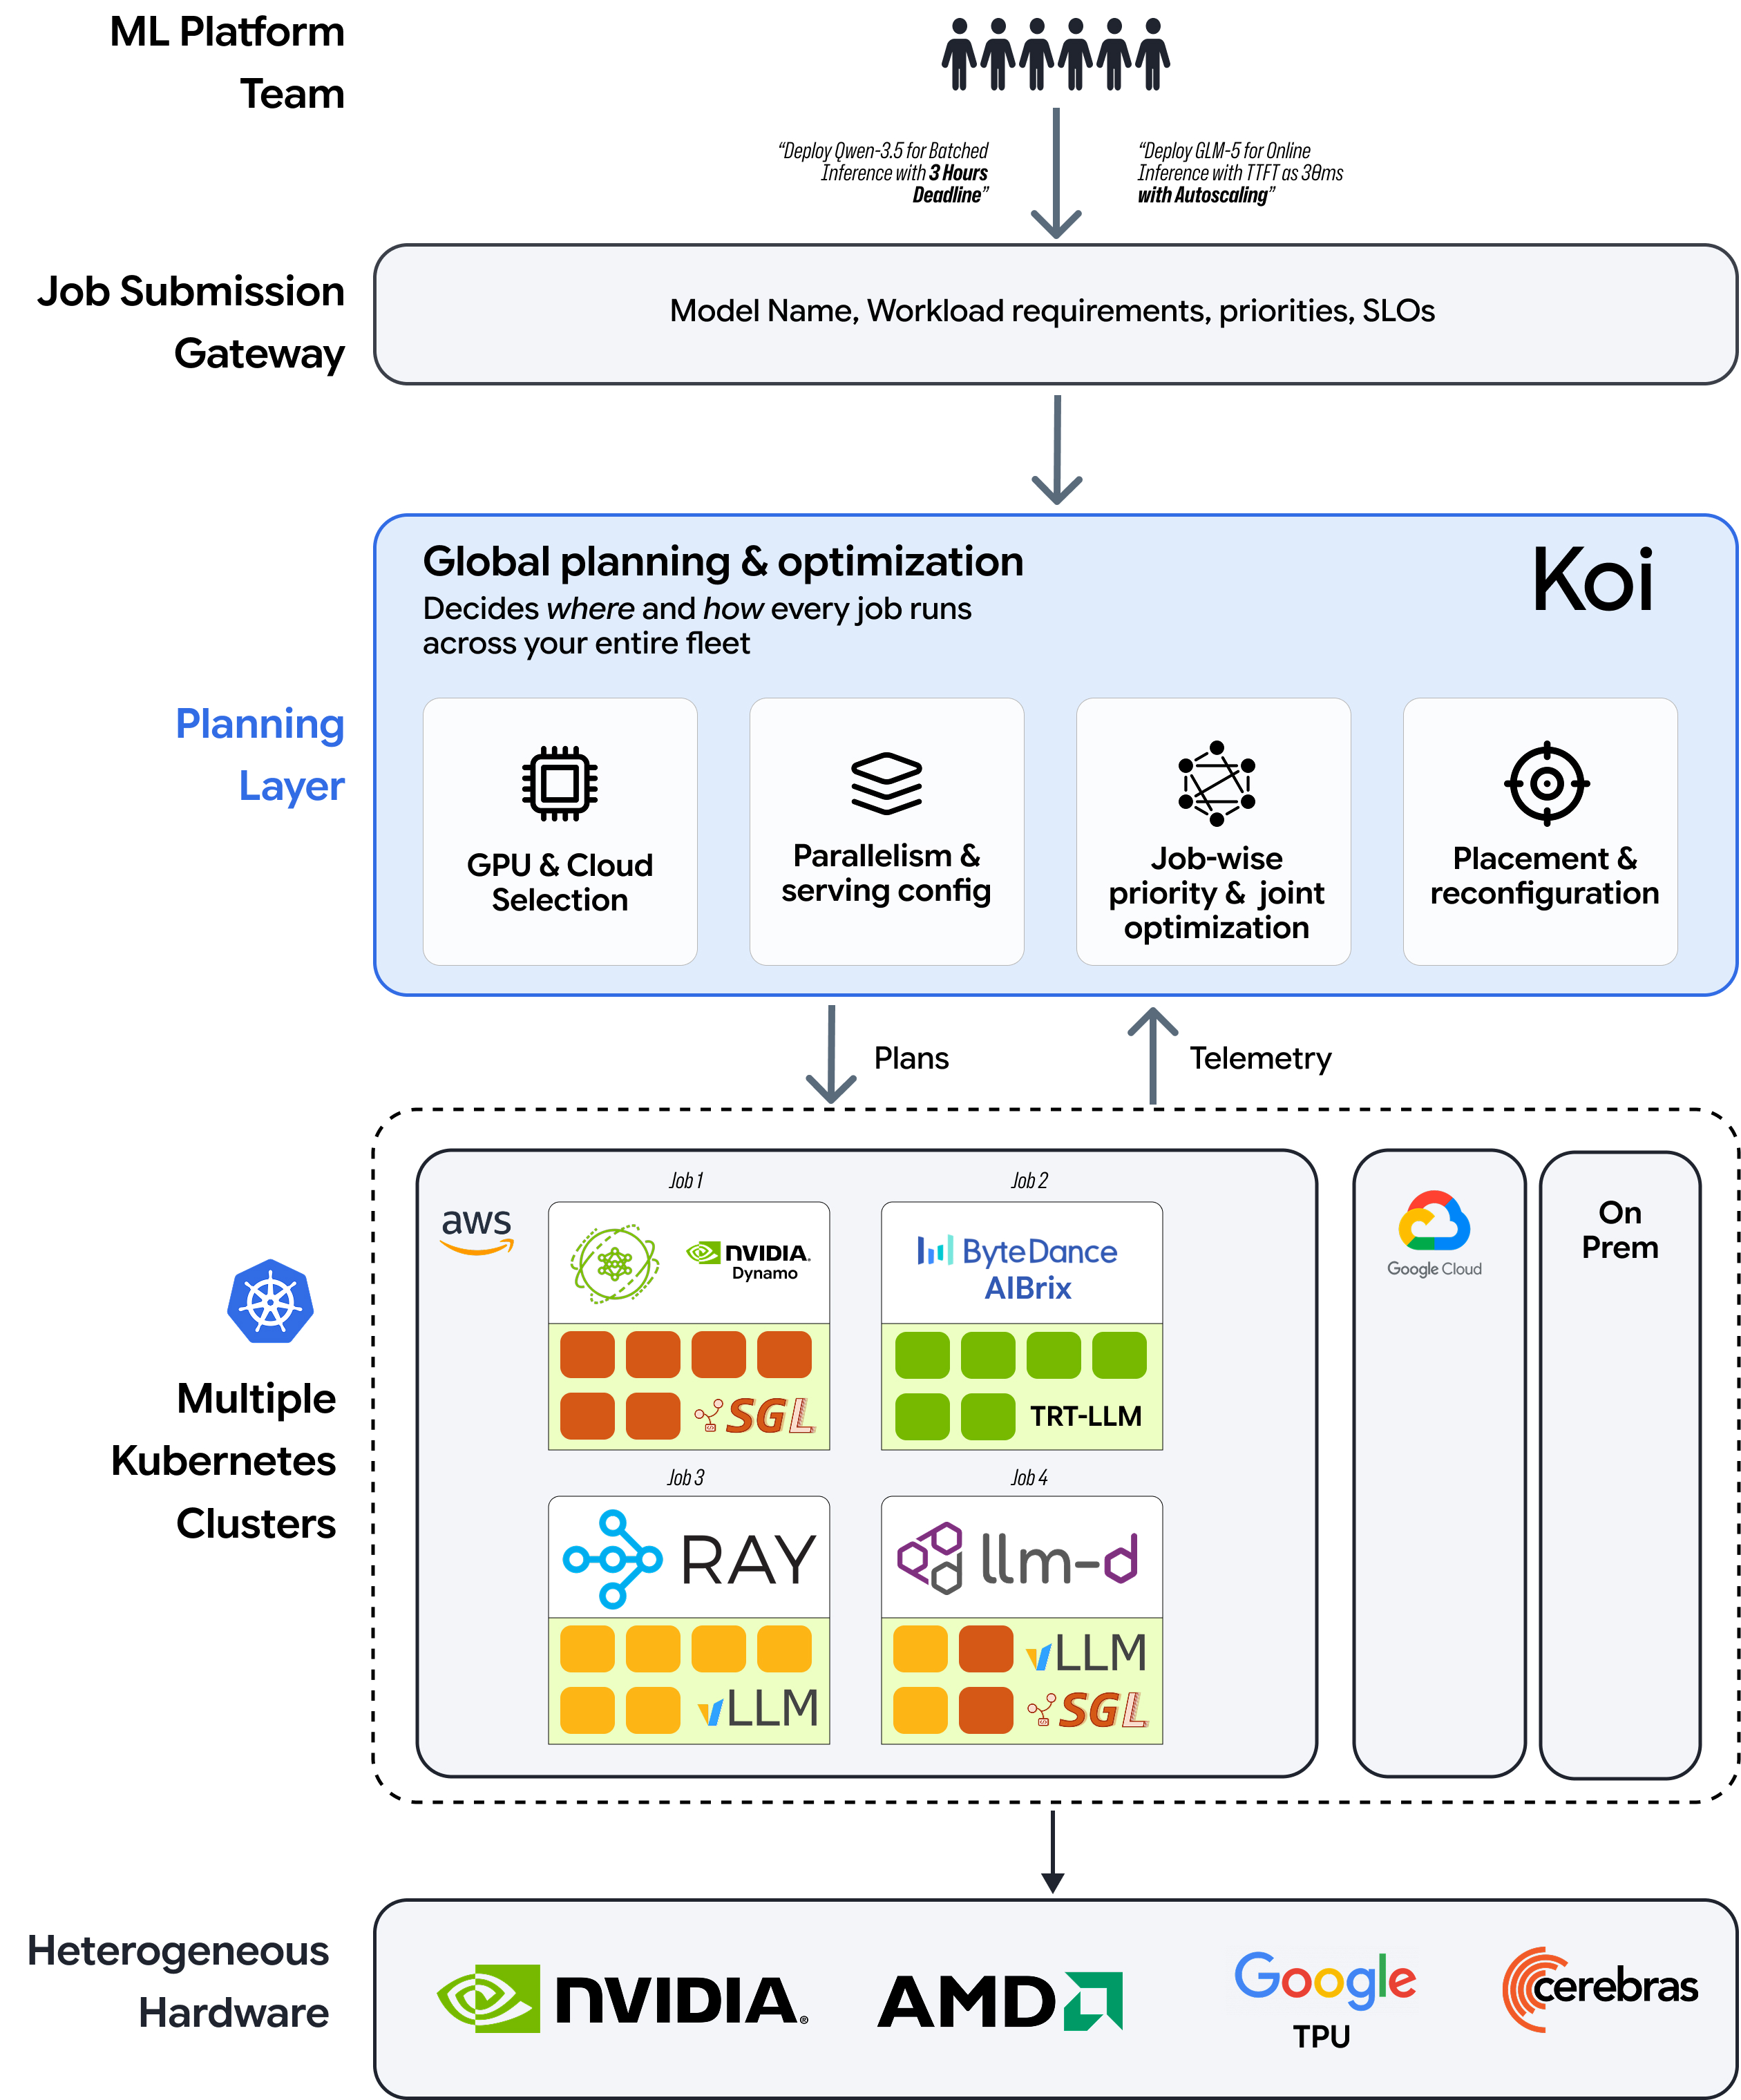 Conceptual view of Tandemn’s planning layer between job submission and the existing cluster and serving infrastructure.
How Koi plans
Section titled “How Koi plans”Koi plans across jobs rather than optimizing each deployment in isolation. A language model can propose candidate deployments, but deterministic components predict and score their behavior, check capacity and serving constraints, and choose among feasible plans. After deployment, Koi compares observed telemetry with its predictions and updates its causal evidence, so later plans can use what the fleet has learned.
This loop is intended to balance useful capacity and job objectives while accounting for constraints such as hardware availability, latency risk, batch deadlines, and the cost of changing active deployments. See Koi: Self-Calibrating Planner for LLM Inference Fleets for the research design and details.
Core concepts
Section titled “Core concepts”| Concept | Meaning | Read more |
|---|---|---|
| Job intent | A model, workload description, and objective, such as online latency targets or a batch deadline. | Job reference |
| Planning tick | One cycle in which Koi observes the fleet and produces a plan. | Koi planner |
| Resource map | A view of available cluster capacity and the status of deployed jobs. | Resource map reference |
| Plan | Koi’s proposed deployment decisions across jobs and clusters. | Plan reference |
Where to go next
Section titled “Where to go next”- For the control plane and per-cluster operator, see Tandemn Architecture.
- For Koi’s planning loop and evidence model, see Tandemn Planner (Koi).
- For the inputs and outputs, see the Job, Resource Map, and Plan references.